Back to Knowledge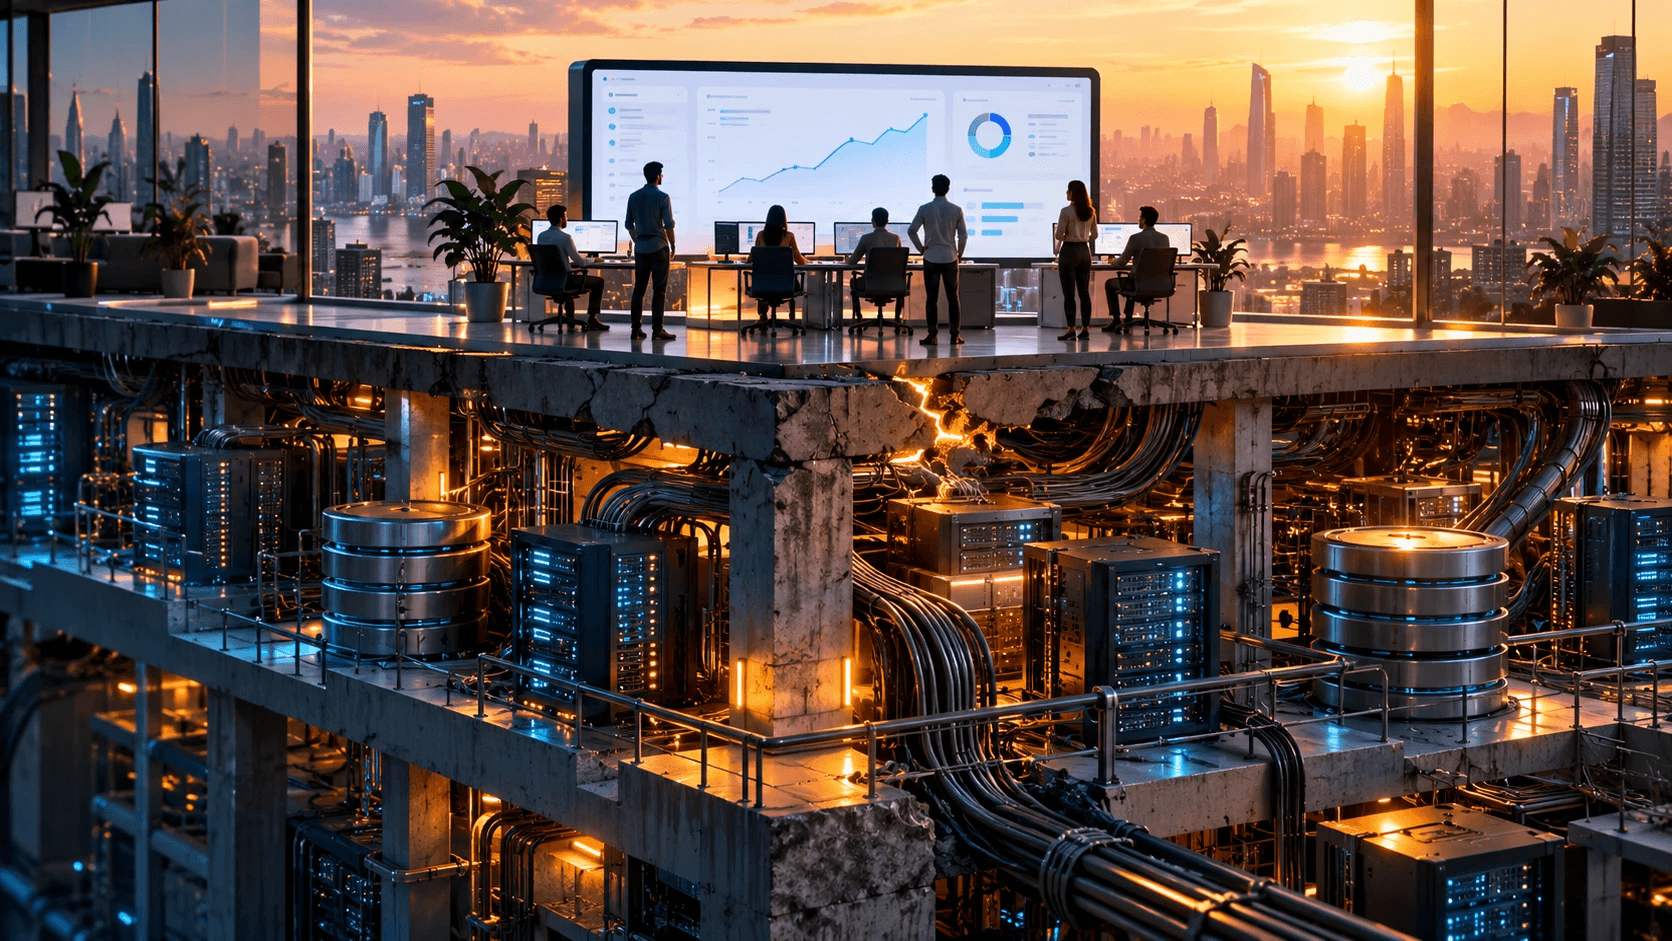
System DesignAI
Sep 20, 20266 min read
The Real Culprits Behind “Engineers Are Slow”
“Why is engineering taking so long?” is often the wrong question. Behind most slow teams is reliability debt, compounding complexity, and MVP shortcuts that borrowed from the future — and good systems engineering often looks like slowness right before it creates speed.
“Why is engineering taking so long?” is often the wrong question. The more uncomfortable question is this: what did we ask engineers to build without understanding what it would cost to make it reliable, maintainable, and capable of surviving success?
I have watched teams celebrate an MVP on Friday and discover an engineering emergency on Monday. The demo worked. The architecture did too, technically. Then real users arrived, traffic increased, edge cases multiplied, integrations started failing, and suddenly the same engineers who had “moved too slowly” were being asked to rebuild the foundation while the building was already occupied.
The problem is not always engineering velocity. Sometimes the organization has confused visible progress with actual progress. Shipping a feature is visible. Designing for failure modes is not. Writing the migration plan is not. Thinking through concurrency, observability, data integrity, security boundaries, recovery procedures, and future load is not. Yet those invisible decisions often determine whether a product accelerates or becomes a permanent tax on everyone who touches it.
This is where MVP thinking can become dangerous when interpreted too literally. An MVP should reduce uncertainty, not eliminate engineering judgment. There is a profound difference between saying, “We do not need every feature yet,” and saying, “We do not need to think about how this system behaves when it matters.” The first is disciplined product thinking. The second is borrowing from the future.
Imagine a team building a payments workflow. For the first hundred transactions, almost anything can look elegant. Then someone clicks twice. A network request times out after the bank processes the payment. A retry arrives. The database commits one record while another service misses its event. Now the team is no longer building a feature. They are reconstructing trust.
Or take a notification system. At MVP scale, one service sends emails directly after a user action. Simple. Fast. Perfect. Then the company grows, users receive more notifications, a provider starts throttling requests, and suddenly a temporary outage blocks critical application workflows because an email system was allowed to become part of the synchronous request path. Nobody necessarily made a foolish decision. They made a locally rational decision without knowing which boundaries would matter later.
That distinction matters because technical debt is not simply “bad code.” Some debt is intentional. You knowingly take a shortcut because learning quickly is more valuable than building perfectly. Reliability debt is different. It accumulates when a system lacks the mechanisms needed to behave predictably under failure, growth, change, or uncertainty. You may not see it in the product demo, but users eventually experience it as downtime, inconsistent data, latency, mysterious bugs, and increasingly cautious releases.
There is a psychological reason organizations underestimate this debt. Humans naturally reward immediate evidence. A feature that ships today produces a dopamine hit. A reliability improvement that prevents an incident six months from now produces nothing visible. The absence of disaster rarely receives applause. So teams can accidentally optimize for what executives can see rather than what systems need.
This creates one of the strangest patterns in technology companies. Engineering appears slow precisely because engineers are finally dealing with the consequences of decisions made when everyone was trying to move fast.
The complexity explosion usually starts innocently. Add one integration. Then another. Add a special case for an important customer. Introduce a background job. Create an exception for legacy data. Add a feature flag. Introduce a second database because the first one cannot handle a particular workload. Connect another service. Suddenly, the architecture is no longer a collection of simple components. It is a network of assumptions.
And complexity does something dangerous: it compounds.
Ten components do not necessarily create ten units of complexity. The difficult part is often the relationships between them. Who owns the data? What happens when service A succeeds and service B fails? Can the operation be retried safely? Which system is authoritative? How do we detect partial failure? What happens during deployment? What happens when traffic is ten times higher than expected?
These are systems engineering questions. They rarely appear in a product roadmap, but they determine whether the roadmap remains executable.
This is why the phrase “just build it” can be expensive. There is always a hidden “and then.” Build the API, and then handle retries. Launch the integration, and then monitor it. Store the data, and then migrate it. Add the feature, and then support it. Increase traffic, and then discover the bottleneck. Every shortcut pushes a future decision into a more expensive context.
None of this means engineers should demand perfect architecture before shipping anything. That would simply replace one failure mode with another. The goal is not maximal engineering. The goal is proportionate engineering.
A prototype does not need a hyperscale architecture. A production payment system probably should not be treated like a prototype.
The best engineering organizations understand this distinction instinctively. They know where to move quickly, where to create deliberate constraints, where to accept debt, and where debt is simply too dangerous to accumulate. They understand that architecture is not an exercise in drawing boxes on a diagram. It is the discipline of managing future complexity before that complexity starts managing you.
There is also a cultural lesson here. When a product organization says, “Engineering is slow,” it can create a self-fulfilling prophecy. Engineers become defensive. Product becomes frustrated. Estimates become political. Teams start adding buffers because they no longer trust the planning process. Nobody talks openly about uncertainty because uncertainty has become socially expensive to admit.
A healthier question is much more specific: What is making this work expensive?
Maybe the requirement is changing every week. Maybe the system has accumulated five years of undocumented assumptions. Maybe reliability work was repeatedly deferred. Maybe the architecture has crossed too many service boundaries. Maybe the team is solving a problem that looked small on a roadmap but is actually a distributed-systems problem in disguise.
Once you ask that question, the conversation changes. Engineers can explain the constraint. Product can challenge whether the constraint is necessary. Leadership can decide what tradeoff the business is actually willing to make. That is engineering reality, not engineering theater.
The irony is that good systems engineering can look like slowness right before it creates speed.
A team that spends time establishing observability may ship faster later because debugging stops being archaeology. A team that designs clean ownership boundaries may move faster because every new feature does not require negotiating with six services. A team that invests in reliable deployment mechanisms may release more frequently because releases stop feeling like controlled explosions.
So the next time someone says, “Engineers are slow,” pause before accepting the diagnosis.
Ask what kind of system they are being asked to build. Ask what assumptions are changing underneath them. Ask what reliability guarantees the business expects. Ask how much complexity has accumulated around the feature. And most importantly, ask what shortcuts were taken earlier that the engineers are now being asked to repay with interest.
Sometimes engineers really do need to move faster.
But sometimes the bottleneck is not the people building the system.
It is the system they were asked to build.
What have you seen create the biggest gap between “we shipped the MVP” and “we have a production system”? I would especially love to hear the engineering debt that looked harmless at first and became painfully expensive later.